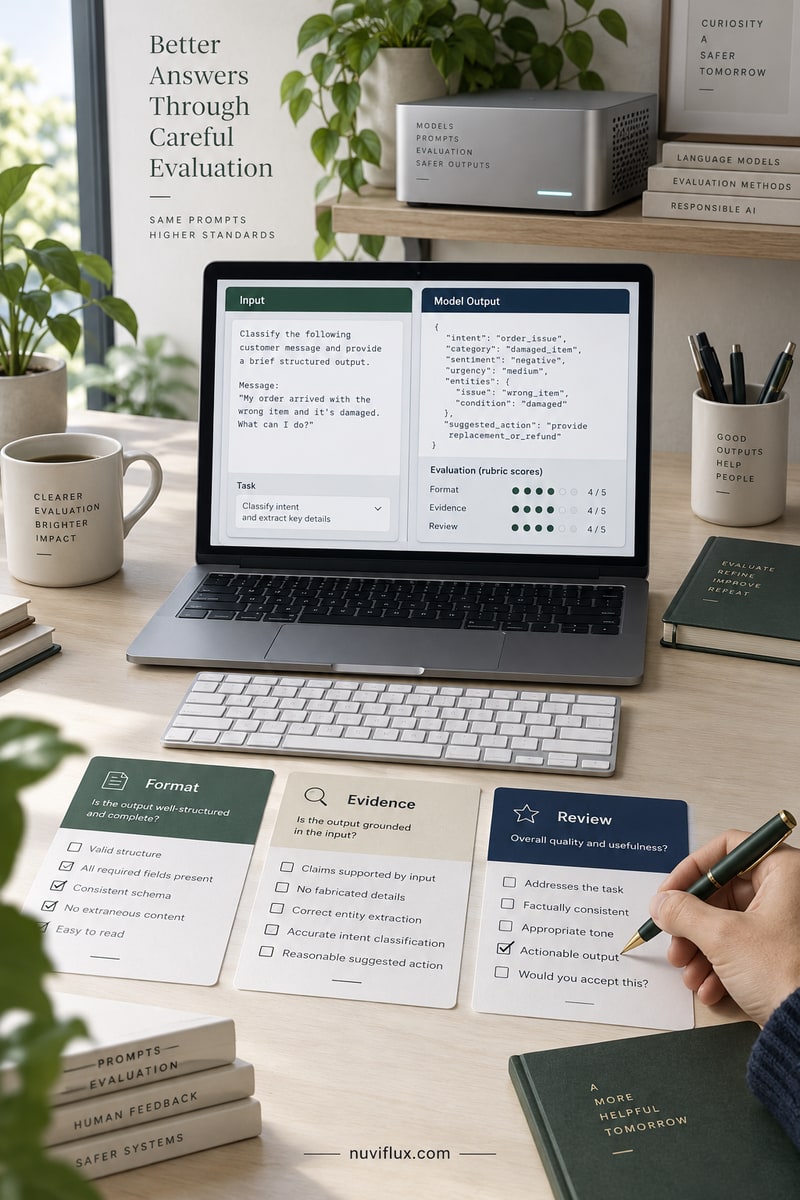
Jev-Based AI Agent Validation Tool
Developers can build a lightweight API service that uses new Jev models to validate and structure outputs from AI agents, ensuring reliability.
Open NuviFlux for the evidence, open questions, and first test.
THE OPPORTUNITY, IN CONTEXT
Explore focused checks for AI agent outputs
The business model
An agent’s response may need a check against a few specific criteria before another system uses it. A developer could add task-specific classification and structured results, while leaving room for human review when the model gets a judgment wrong.
What has been observed
The simple-jev documentation describes next-token scoring with server-constructed JSON and an existing classifier API. It supports defined question types, but a well-formed response does not prove factual correctness or calibrated confidence. A generic API wrapper alone may add little value.
Entry conditions and costs
Costs include model downloads, compatible compute, setup and evaluation examples. Model terms are separate from the code license. Public exposure also needs authentication and transport protection beyond the documented local server.
The key question
Do the classifications help enough to justify the integration and review costs?
Common questions
Does valid JSON mean the answer is correct?
No. Structure and task correctness need separate evaluation.
Does the health endpoint test inference?
No. A successful health response is not a successful classification test.
A CLOSER LOOK
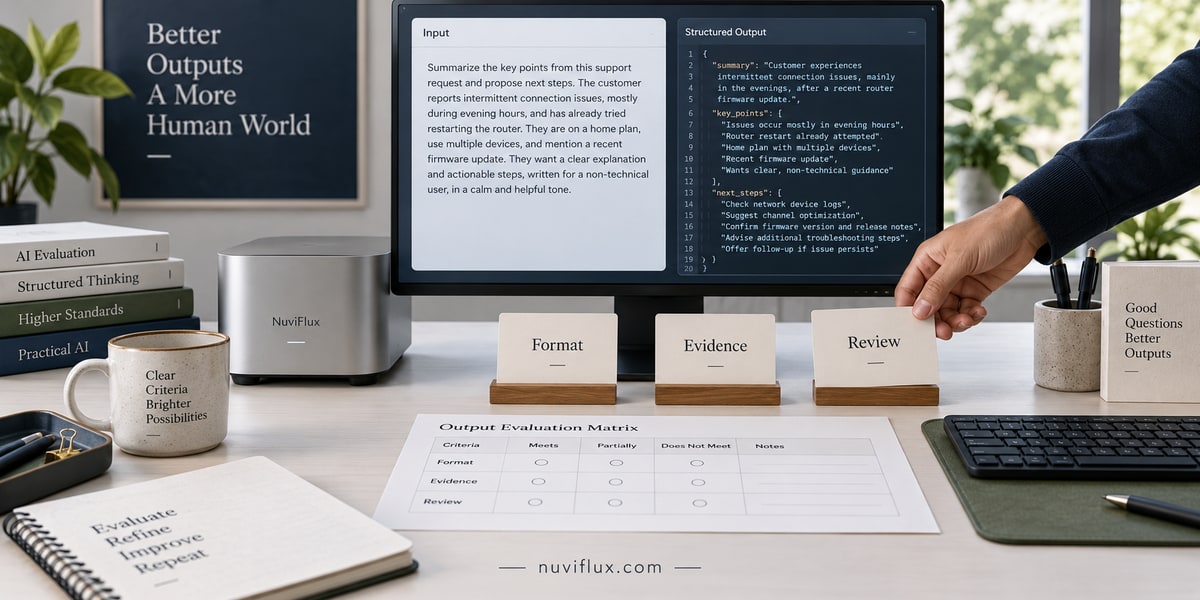
Check the structure—and the judgment
Agent responses can be classified against specific criteria before another system uses them. Developers could sell task-specific checks that return structured results for review.